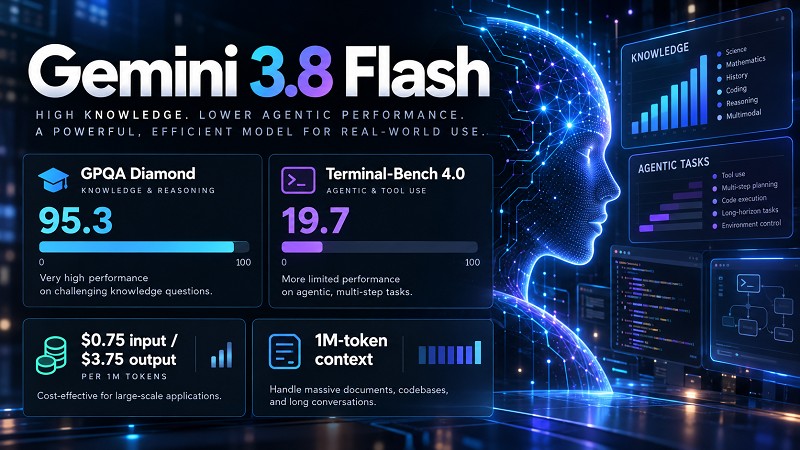
Gemini 3.8 Flash scores 95.3 on GPQA Diamond — the highest knowledge reading in this batch — and 19.7 on terminalbench_v4_0, roughly where the cheapest cards sit [OURS]. The same model, on the same card, at $0.75 input and $3.75 output per million tokens. The gemini 3.8 flash price query lands on that table. The card is served by OrcaRouter.
The ten rows
| Row | Score | Source |
| GPQA Diamond | 95.3 | artificialanalysis.ai |
| terminalbench_v2_1 | 87.6 | artificialanalysis.ai |
| HLE-Verified | 54.9 | deepmind.google |
| Long-Context Recall | 81.3 | artificialanalysis.ai |
| AA Coding | 76.3 | artificialanalysis.ai |
| SciCode | 56.6 | artificialanalysis.ai |
| Humanity’s Last Exam | 47.8 | artificialanalysis.ai |
| tau_banking | 44.9 | artificialanalysis.ai |
| AA Intelligence | 40.9 | artificialanalysis.ai |
| terminalbench_v4_0 | 19.7 | artificialanalysis.ai |
Eight of the ten rows are the evaluator’s; one is Google’s own; one is the intelligence index.
The two ends of the table
GPQA at 95.3 is not a marginal lead. The Fable cards read 92.6 and 93.7, Qwen3.8 Max 92.8, GPQA’s usual band in this catalogue is 85 to 93. A Flash-tier model at the top of the knowledge table is the specific thing this card is claiming.
terminalbench_v4_0 at 19.7 is the counterweight. The hardest generation of that benchmark separates models sharply, and 19.7 is in the band occupied by older or smaller models — the Fable cards read 42 to 52, the GLM cards 32 to 42, DeepSeek’s v4.1 at 33.8.
Read together, the two rows describe the same split the rest of the table shows: knowledge and instruction-following at the top of the catalogue (GPQA 95.3, IFBench not listed but terminalbench_v2_1 87.6 and Long-Context Recall 81.3), agentic execution in the lower half (tau_banking 44.9, v4.0 19.7).
A second, quieter pair
The card prints Humanity’s Last Exam twice — at 47.8 from the evaluator and at 54.9 from Google DeepMind under the name `HLE-Verified` [INDEPENDENT and VENDOR].
Two publishers, two configurations, 7.1 points apart. That is a smaller gap than most card pairs show, and it cuts the same way as the rest of the table: the vendor’s harness is the friendlier one, and the difference is modest enough that both numbers describe the same model.
The rate row
| Line | Rate per million | Against input |
| Input | $0.75 | 100% |
| Output | $3.75 | 500% |
| Cached read | $0.075 | 10% |
A 5× output ratio and a 10 percent cache read, with no cache-write rate published [OURS]. The envelope is a 1,048,576-token context with a 65,536-token output ceiling — the same shape as its 3.5 Flash predecessor, at half the input price.
Half. Gemini 3.5 Flash charges $1.50 and $9.00; this card charges $0.75 and $3.75. Same envelope, same cache-read structure, half the money — and the newer card is the one with the 95.3 on GPQA.
Telemetry: two extremes at once
Seven-day figures report 7,924 ms median time to first token — the slowest start in this batch — and 610.8 output tokens per second, among the fastest [OURS]. The error rate is 4.00 percent and traffic was 50,597,855 tokens.
That combination is not a contradiction. A Flash-tier model taking eight seconds to produce its first token is queueing; once it starts, it generates fast enough to finish a long answer in seconds. The p95 sits at the 10,000 ms recording ceiling, so the slow tail is unmeasured rather than bounded.
For a workload, the shape matters more than the average: a 600-token answer takes 8 seconds to begin and one second to write; a 4,000-token answer takes the same 8 seconds and six and a half seconds of writing. Long outputs amortise the wait, short ones do not.
What the card is actually for
Knowledge-heavy work with short answers. GPQA 95.3 and a half-price rate row make this the cheapest route in the batch to top-of-catalogue knowledge scores.
Reading at scale. A million-token context at $0.75 input is about as cheap as large-context reading gets here.
Not agents. The v4.0 row and tau_banking’s 44.9 both say the model stops when the task requires sustained execution against an environment.
The takeaway
Gemini 3.8 Flash prices at $0.75 input, $3.75 output and $0.075 cached per million tokens, with a 1,048,576-token context, a 65,536-token ceiling, and 95.3 on GPQA Diamond [OURS].
The same card reads 19.7 on terminalbench_v4_0. It is the strongest knowledge-per-dollar card in this batch and one of the weakest on the hardest agentic benchmark — a split a buyer should route around rather than average away.
Sourcing note: all ten benchmark values and their `source` fields, the three rates, the context and output ceilings, the FAQ and section counts, and the seven-day p50, p95, error rate, output speed and token total are read from the OrcaRouter public model card for `google/gemini-3.8-flash` on 2026-10-23 [OURS]. Rows tagged artificialanalysis.ai are that evaluator’s runs [INDEPENDENT]; `HLE-Verified` is tagged deepmind.google [VENDOR]. The comparison to other cards’ terminalbench_v4_0 readings, the price comparison to Gemini 3.5 Flash and the routing advice are our own. The impression figure is Search Console for the 28 days to 2026-10-21 [OURS]. No competing gateway or inference marketplace is named. All values checked 2026-10-23.